Configurator audit · 12 November 2026
Four order flows, one watch, walked by an agent
An agent walked each flow on an iPhone-sized screen as two scripted buyers: one who knows what she wants and builds the same watch in every flow, and one in a hurry who accepts the defaults and never looks for the wrist size. A third, who opens everything, was added after the review. It recorded every tap, screenshots of the key screens and a set of checks. A second pass fixed what was cheap to fix and ran everything again. Then an independent agent checked this report and the flows, and found more. Those findings are at the end, with the corrections they forced.
How to read the numbers. These are machine walkthroughs of an interface. They say how much work a flow asks for and where it breaks. They say nothing about how many people would order. That is what the test is for.
Recommendations first
What to do, in this order
Test flow B against flow A first
A is the classic wizard, B the single page with a running total. Both are full configurators for a custom build, and they differ clearly in effort: 14 taps against 8 for the same watch. Flow A is the control. That most shops choose between these two patterns is our assumption, not something measured here.
Before any test, deal with the required choice
Three of the four flows only noticed a missing wrist size at the very end. That would have polluted every comparison, because a flow could lose on one late error instead of on its design. Two fixes are in, one question stays open (finding 2).
Hold flows C and D for round two
C is expensive for a full custom build and D makes a different bet, about advice instead of layout. Test them once there is a winner between A and B, D first and only on gift traffic.
Evidence
Scoreboard
Same target watch in every flow: rose gold, green dial, white seconds hand, leather, medium, engraving "FOR MEI". Screen 390 by 844, touch.
A · Step by step
Missing size is caught in the step itself. Price and next button visible on all 7 steps.
B · One page
Missing size is caught at review. More than 1,000 px of scrolling. Wrist size was not on the first screen in the first run.
C · Tap the watch
Missing size is caught at review. Every part costs three taps: open, choose, done. The 3D stage fills about three quarters of the screen.
D · Guided
Missing size is caught at review. Three answers produced four of the seven target choices. No price on screen during the questions.
Extra taps are counted by one rule in every flow: the taps needed to repair the mistake, without the final continue that was needed anyway. All 48 runs so far reached a finished order with no script errors and no horizontal scrolling. The tap counts did not change after the fixes, which is expected: the fixes are about visibility, not about route length.
Findings, each with its source
What the agent found
Flow A: the error for a missing size was off screen
The hurried buyer pressed Next without choosing a size. The flow stopped, correctly, but the message was drawn under the last option, behind the order bar. On screen nothing appeared to happen.
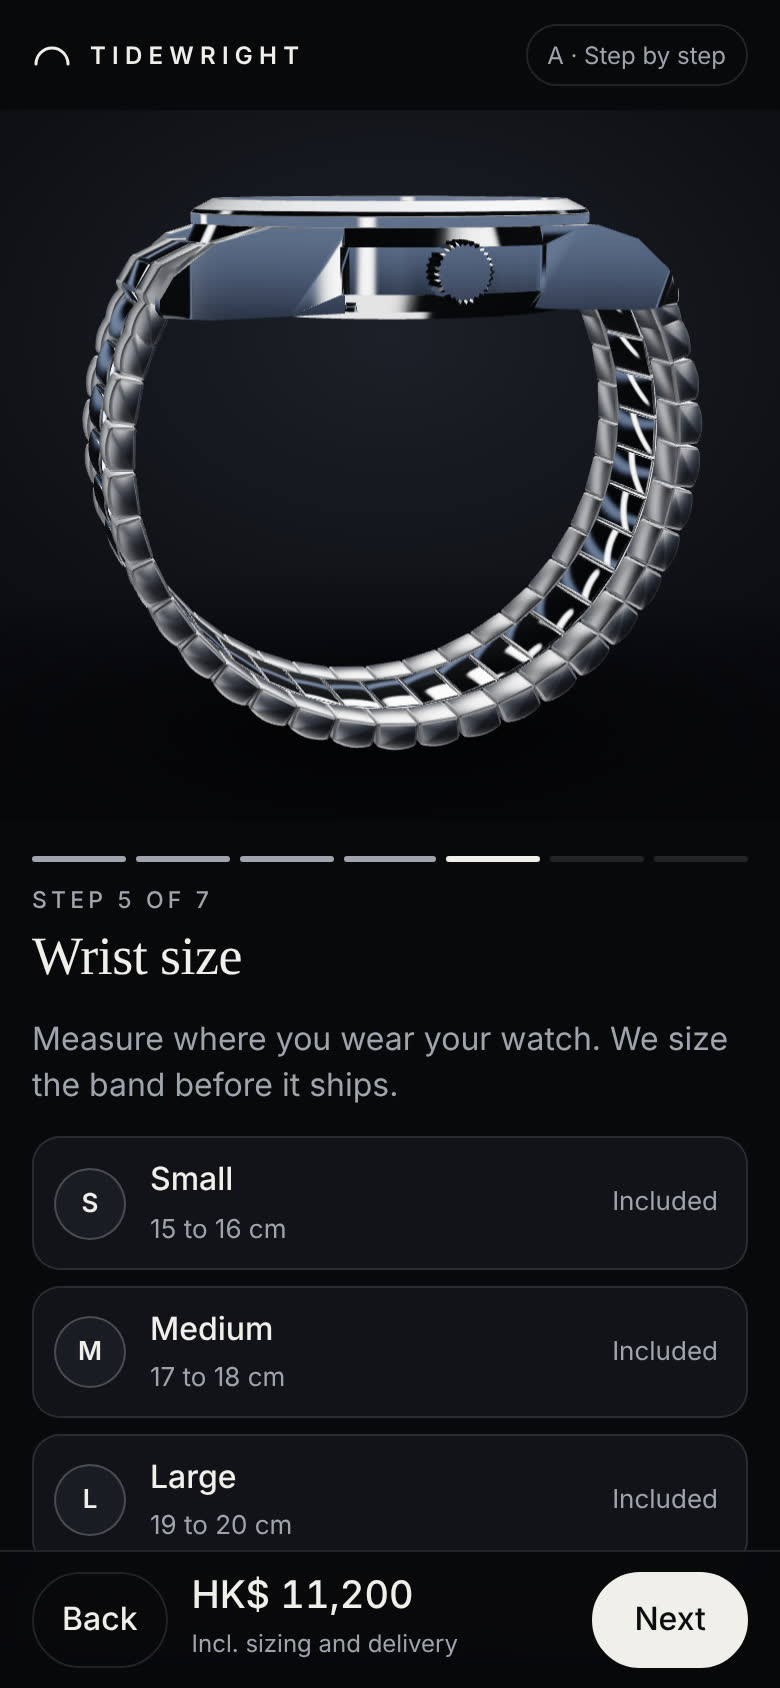
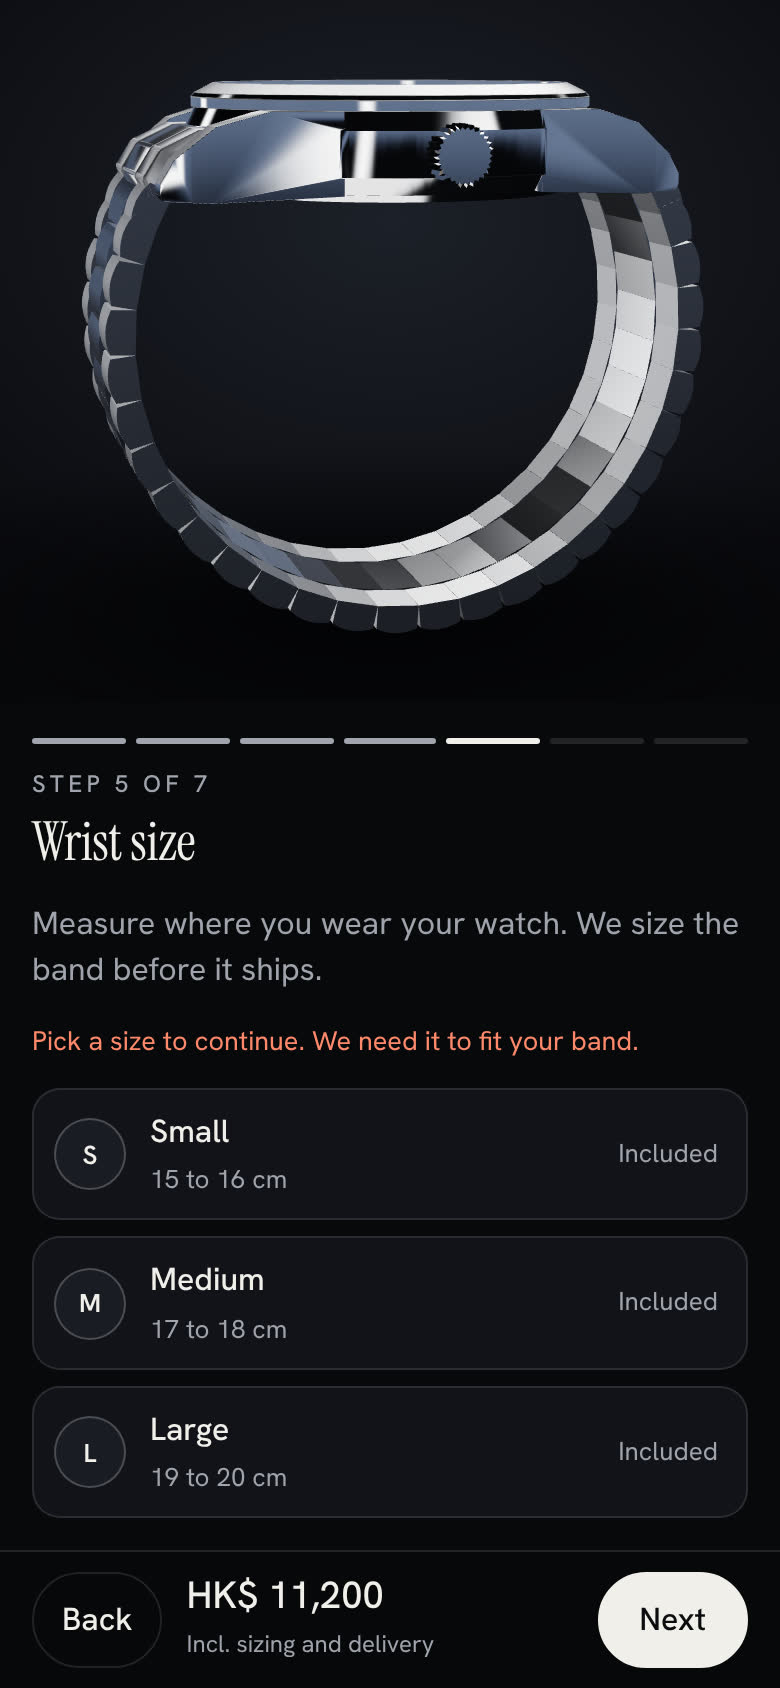
Source: screenshot a-hurried-01, before and after. The after run records the message inside the visible area (errorInView: true). The first run did not record that field yet, so for the before state the screenshot is the evidence. Related guideline: WCAG 2.2, 3.3.1 Error Identification.
Flows B, C and D find the missing size only at the end
In all three the buyer reaches the review and presses Continue to delivery. Only then an error appears, and the buyer has to tap the row to go and fix it. The repair took 3 to 4 extra taps, against 1 in flow A.
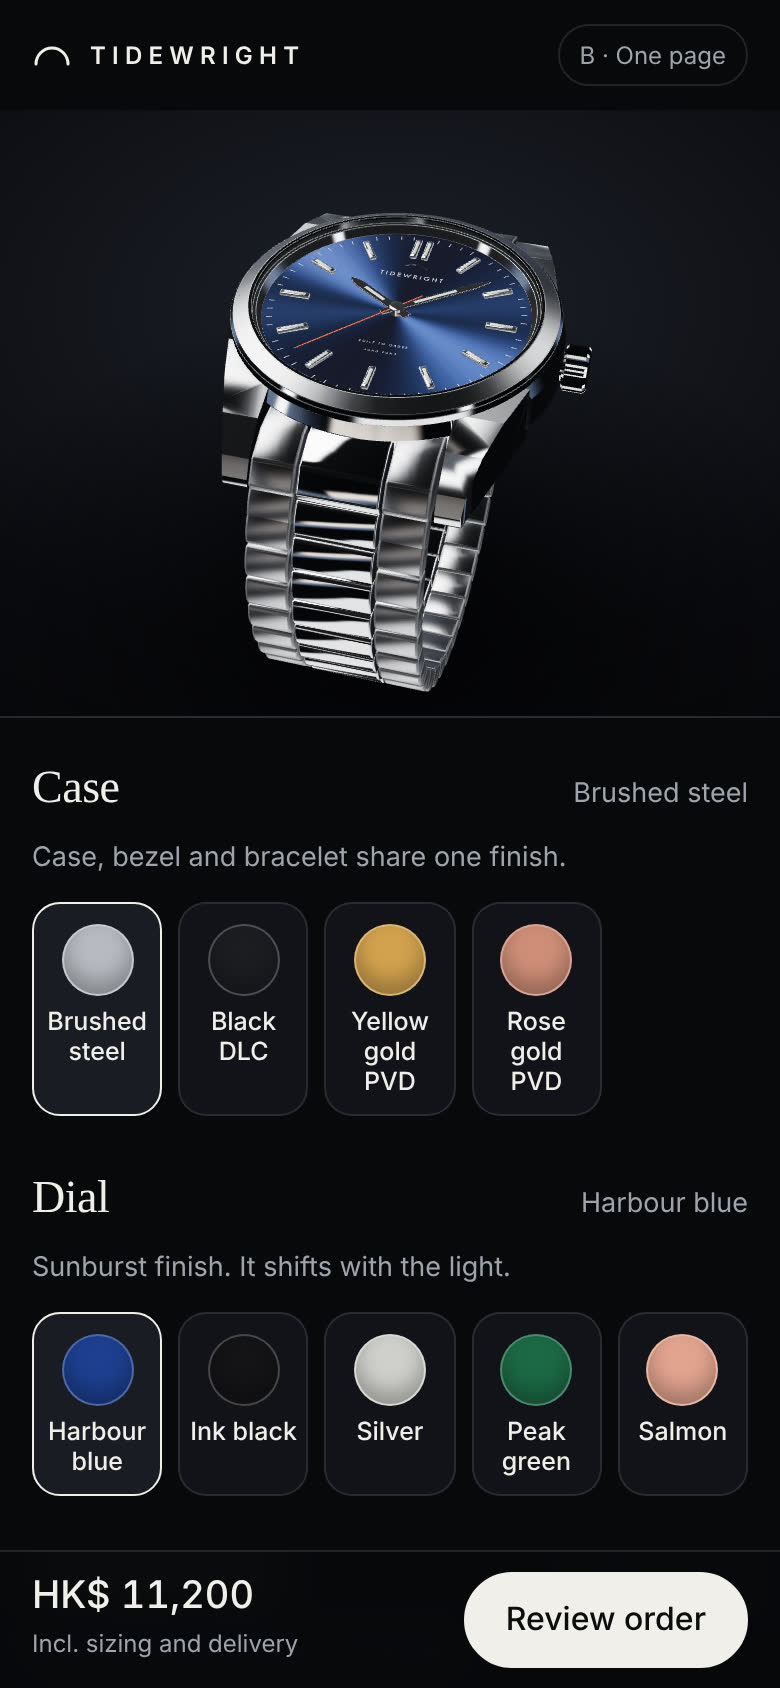
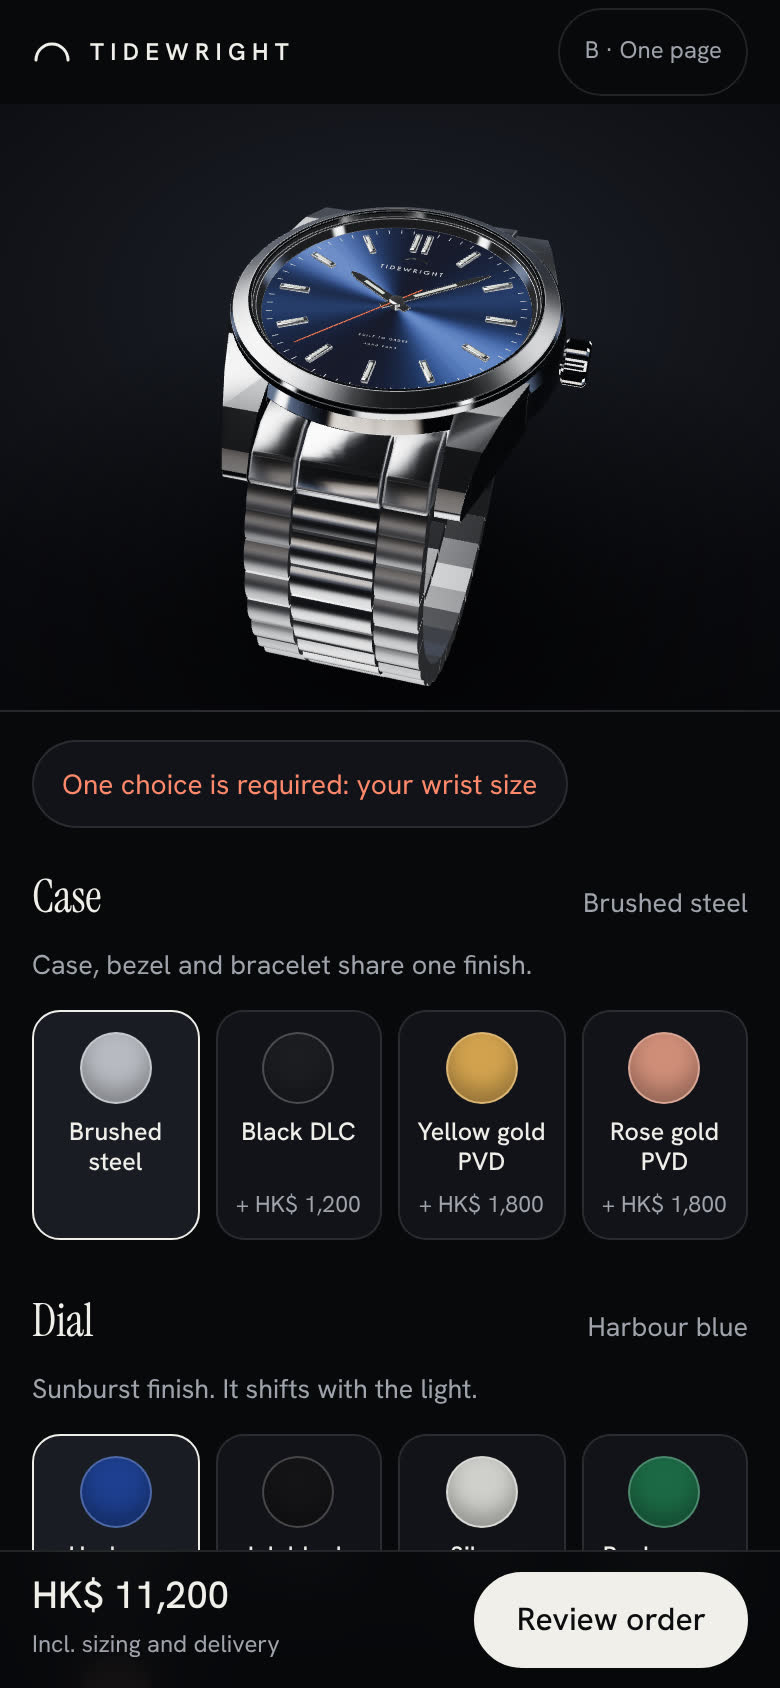
Source: hurried runs in data.json (sizeCaught, recoveryTaps) and screenshots b-hurried-01, c-hurried-01, d-hurried-01. Fixed: B announces the choice at the top, D lists it first in the suggestion. The recovery numbers are unchanged after the fix because the scripted buyer ignores hints by design.
Question for the team
Should the review button stay active while a required choice is open? Blocking it earlier is the obvious fix, but it is a product decision, not a bug.
Flow C costs 20 taps for a full custom build
That is two and a half times flow B for the same watch. Each part needs open, choose, done. Wrist size cannot be tapped on the watch at all, and the engraving only after turning the watch over.
Source: decided runs in data.json: C 20 taps, B 8, A and D 14.
Question for the team
Is this flow meant for people who change one or two things on a ready-made watch? Then it should start from presets, and the comparison with A and B is not a fair one.
Surcharges were invisible in the swatch grids
In the swatch grids a paid finish looked the same as an included one (seen in flows B and C; flow D uses the same component). The total changed after the tap, without an explanation next to the choice.
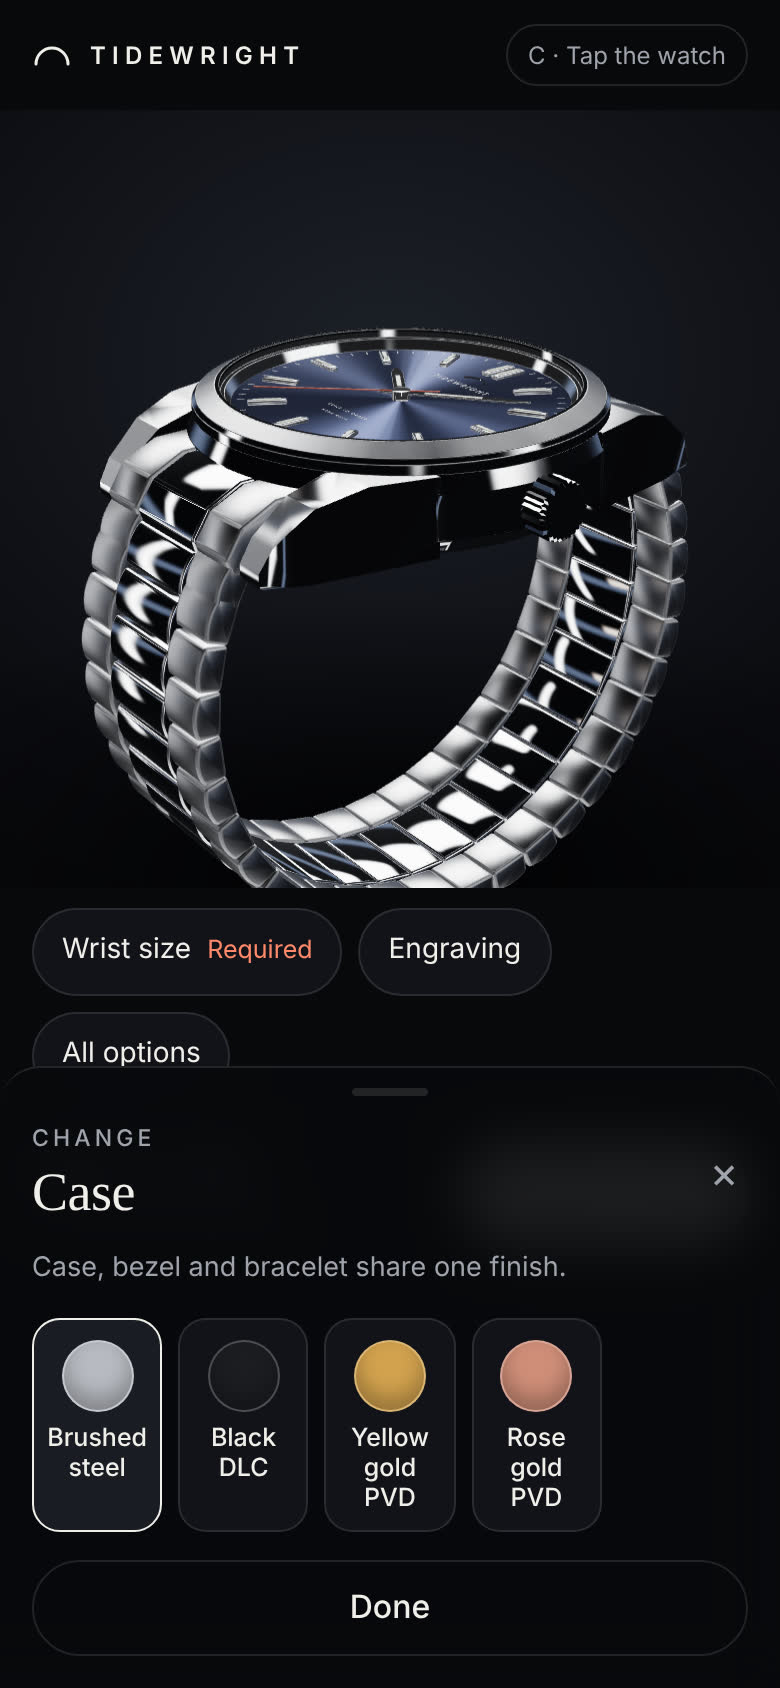
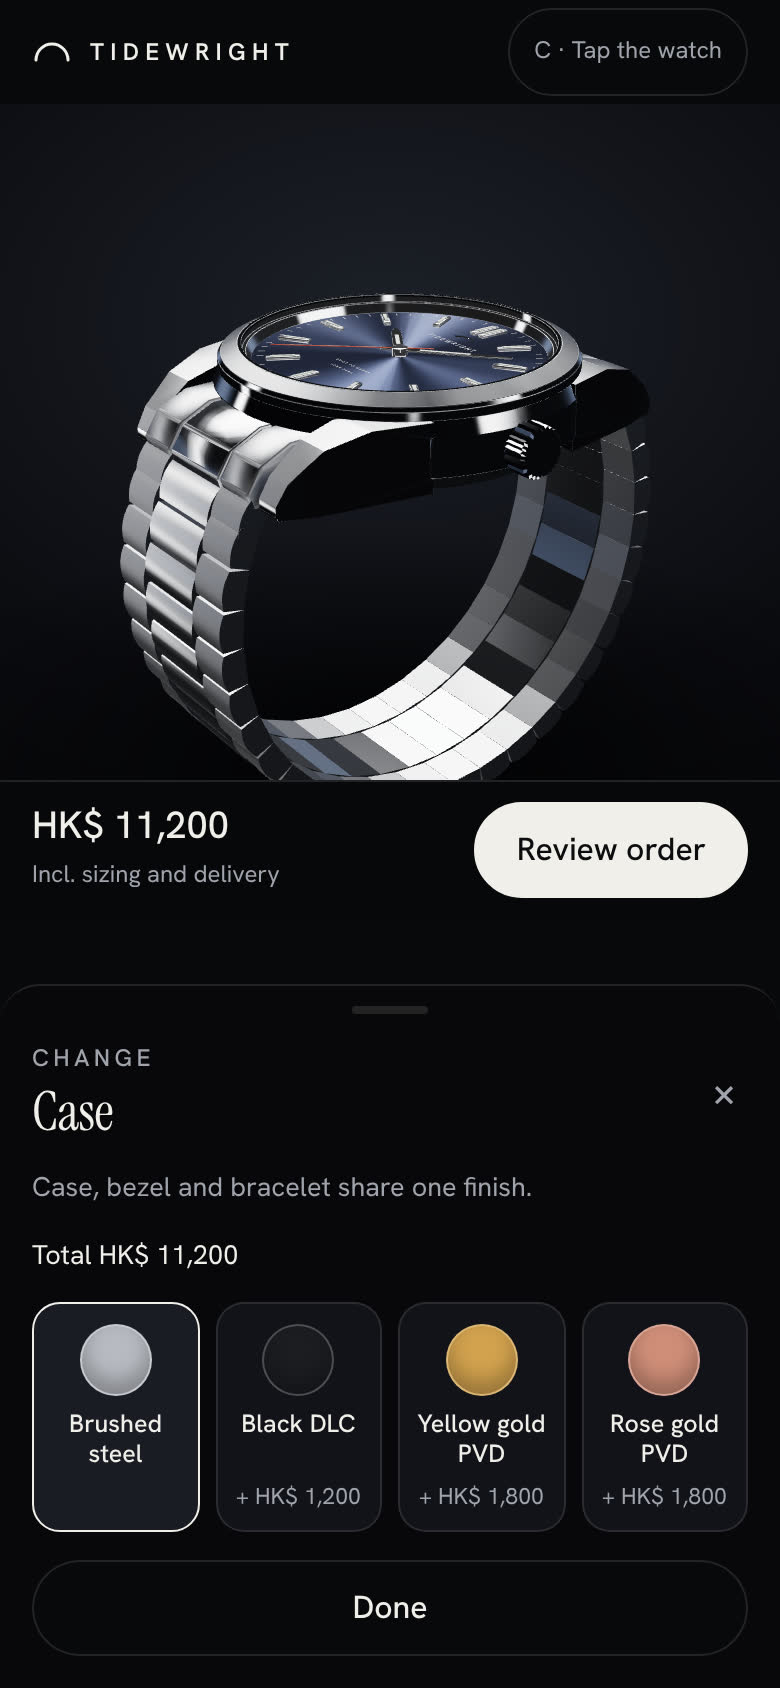
Source: screenshots c-decided-02 and b-decided-01, before and after. The compact tile first showed the surcharge without the currency. It now shows it in full, like the list.
Assumption
That an unexplained change in the total costs trust is our assumption. It is not measured here.
Flow A: the only paid dial sat below the fold
On step 2 the fifth dial, Salmon, was hidden under the order bar on an 844 px screen. It is the only dial with a surcharge. It stayed open as a question at first. After the owner's review it was fixed: groups of five or more now show as tiles, so every dial is in view with its surcharge.
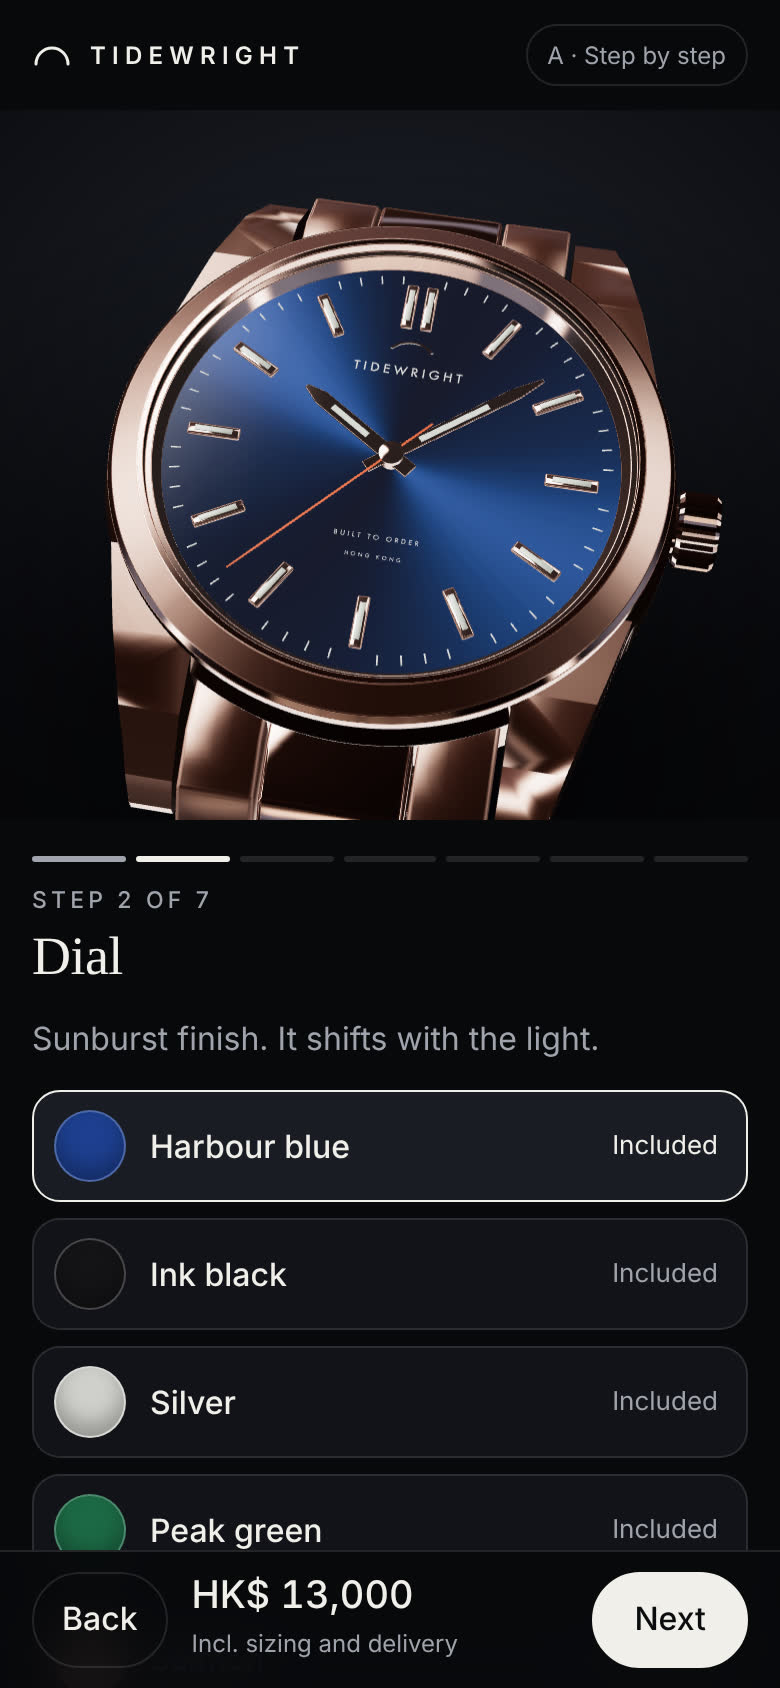
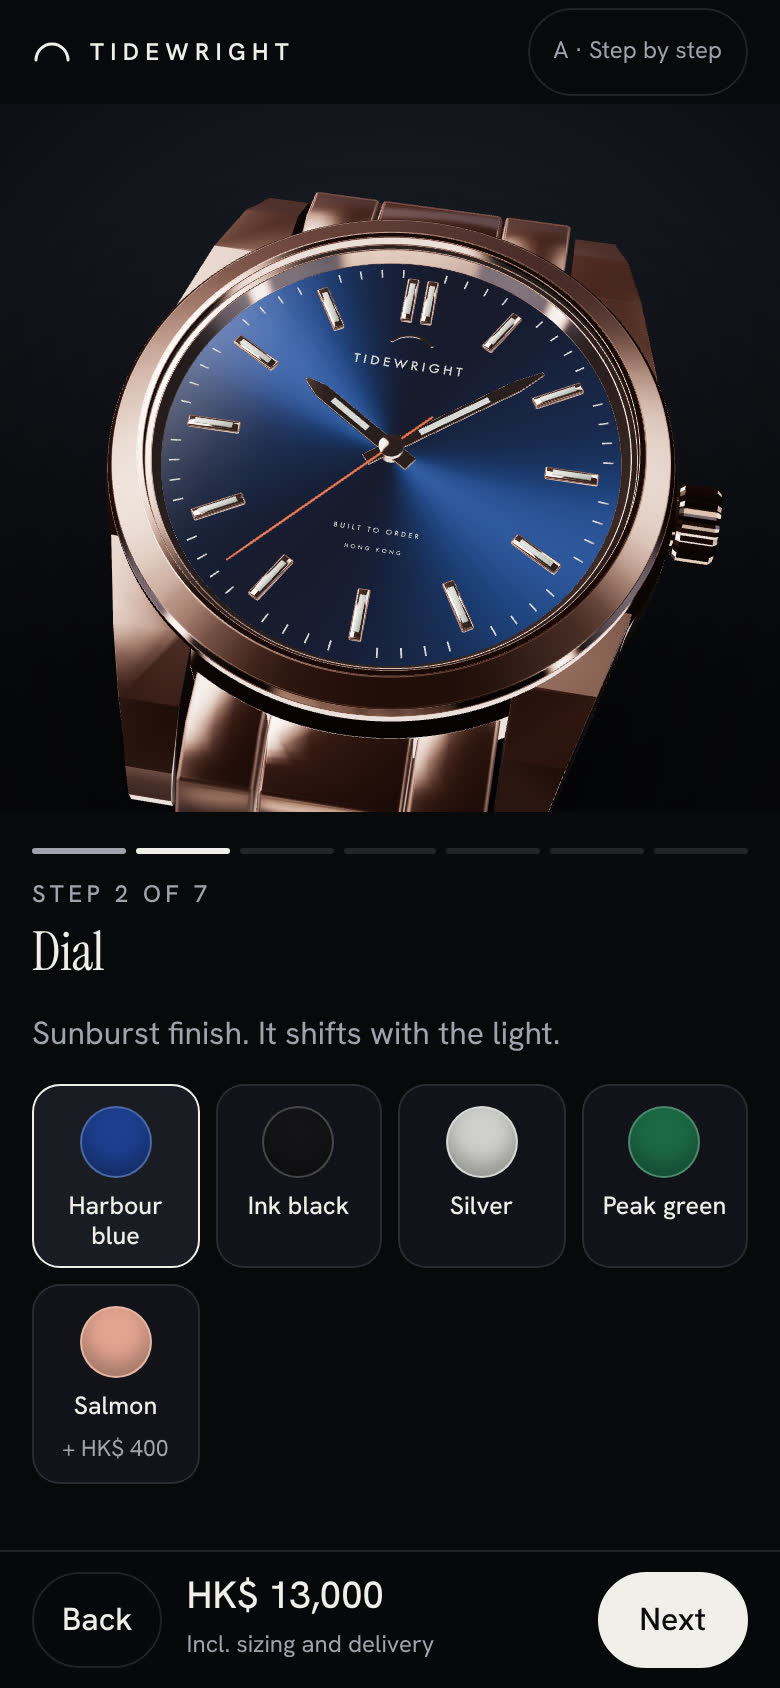
Source: screenshot a-decided-02-step2-dial, before and after.
Three links were smaller than a fingertip
The flow label in the header was 31 px high, the brand link 12 px, and the skip link in flow D 20 px.
Source: smallTargets in before/data.json on the screens where the header was in view. After the fix the list is empty. Guideline: Apple Human Interface Guidelines, which advise touch targets of about 44 by 44 points.
The engraving preview was hard to read
The caseback was shown at an angle, so the text a buyer had just typed was tilted, with a dark case around it. In flow D one label sat only about 8 px from its value.
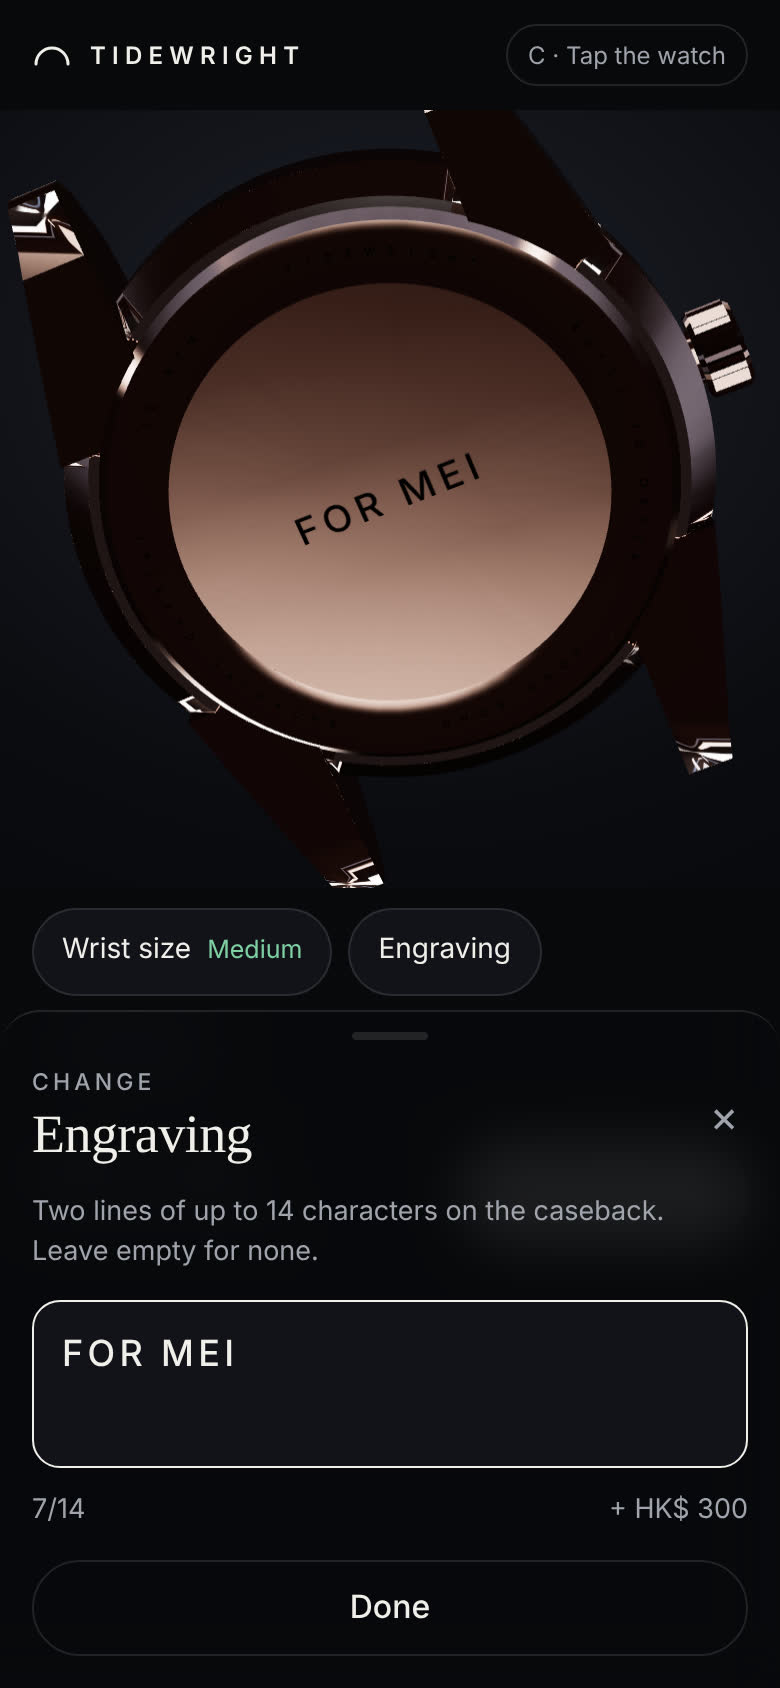
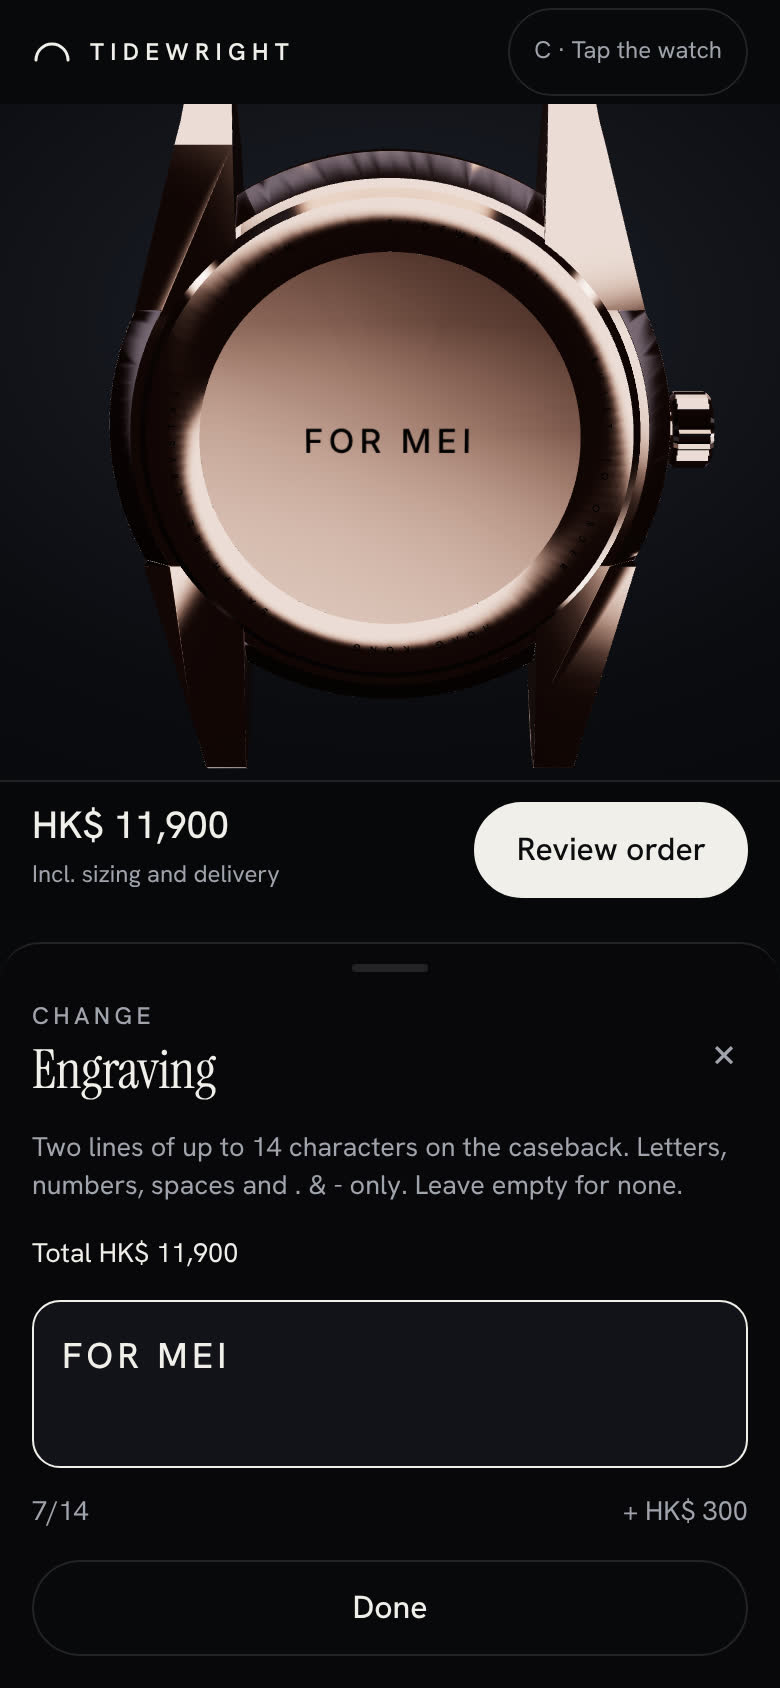
Source: screenshots c-decided-05 and d-decided-06, before and after.
Flow D shows no price during the three questions
Source: priceVisible is false on screens d-decided-01 to 03.
Question for the team
This reads as a deliberate choice, advice first and price second. Is it? For a gift buyer with a budget it may be the first thing she wants to know.
- No horizontal scrolling on any screen, in any flow.
- No script errors in 48 agent runs. A separate walkthrough test (_dev/walk.mjs) completes all four flows with Reduce Motion on and finds no sideways scrolling at 320 px wide.
- No text below a 4.5 to 1 contrast ratio outside the 3D stage. Text drawn over the 3D stage was not measured, because its background changes with the watch.
Checked by an agent that did not build it
What the second agent found
An independent agent got the report, the data and the flows, with the instruction to find what is wrong. It found a serious bug the first audit walked straight past, and four claims in this report that did not hold.
Flow C froze when the bezel was opened
The first audit never opened the bezel in flow C, because the target watch did not need it. The second agent did, and the page stopped responding for more than a minute. The cause sat in the 3D viewer: it scheduled a second render inside every frame, so every camera move multiplied the work.
Source: the reviewer measured about 1,000 render calls for one camera move where about 45 were needed. After the fix, _dev/loop-test.mjs counts at most 13 renders per move and none at rest, and dragging the watch still works with mouse and touch. The walkthrough test now opens every hotspot.
What changed in the agent: a third buyer, the curious one, now opens every option group in every flow and picks the last option. 28 of 28 groups open, every paid choice moves the total, and all four runs finish. Changing everything costs 15 taps in A, 9 in B, 23 in C and 24 in D, where each change is its own sheet.
The engraving field lost text without saying so
Wide letters were cut off on the caseback. Characters outside A to Z disappeared silently, so a name with an accent came out wrong. A long paste was cut at 14 characters, and the caret jumped to the end while typing.
Source: reviewer's reproduction steps, confirmed in _dev/engraving-test.mjs. Now the text scales to fit, a message says what cannot be engraved, a long paste wraps to the second line, and the caret stays put.
Three smaller breaks
- Flow B kept saying a wrist size was required after a reload, although one was chosen.
- In flows C and D the tallest sheet cut off its own Done button.
- The skip link in flow D led into flow B. In a real test that would have counted D visitors as B orders.
- In flow A, changing one choice from the review meant walking every remaining step again. It now goes straight back to the review.
Source: reviewer's steps and after/shots/c-decided-04-sheet-size.
An open sheet covered the running total
In flows C and D the taller sheets hid the order bar, so a buyer saw the surcharge of an option but not the new total. The sheet now carries the total itself and updates it with every choice.
Source: priceVisible is false on the sheet screens of flows C and D in after/data.json, which is the order bar being covered. The total inside the sheet is visible on after/shots/c-decided-02-sheet-case and d-curious-02-sheet-bezel-stone-set.
Corrections to this report after the review. It said A against B was the largest gap in effort; the largest is B against C. It counted the repair taps by two different rules; they are now counted by one, which changed 4 to 5 into 3 to 4. It said the buyer was sent back; an error appears and the buyer has to act. It called two patterns the most common without a source; that is now labelled as an assumption. One of this page's own label colours was below the contrast it checks for, and has been darkened.
Test plan, as hypotheses
What we would test
Test 1: A against B
Hypothesis: showing every choice on one page with a running total leads to more finished orders than one choice per screen.
Primary measure: orders per started build.
Guardrails: average order value, because flow A gives every paid option its own screen and flow B does not. And errors at review.
Test 2: D against the winner, gift traffic only
Hypothesis: buyers who choose for someone else finish more often when they get a suggestion to adjust than when they start from a blank build.
Not yet: C
First decide what flow C is for (finding 3). As a way to tweak a preset it may be the best of the four. As a full configurator it is the most work.
Assumption
That fewer taps lead to more orders is a hypothesis. No uplift is predicted anywhere in this report.
Limits
What this audit cannot tell you
- The buyers are scripts. They do not hesitate, compare or change their mind.
- One screen size, one browser engine, software rendering. Real iPhones were not part of the run.
- The checks are heuristics. A clean check is not proof of a good screen, only the absence of one kind of problem.
- The first run was taken with fallback fonts, because the web fonts could not be reached from the test machine. The fonts are now served by the site itself and the last run uses them. Sizes in the first run are fallback-font sizes.
- In the first run the price and button checks did not notice when a sheet covered the order bar. The agent now does.
- Tidewright is fictional, so there is no traffic, no data and no business context to weigh findings against.
Raw material: before/data.json, after/data.json, the agent itself in agent.mjs, and 77 screenshots in before/shots and after/shots.